AI token costs for prospecting: model routing and your own keys
AI token costs for sales prospecting, explained: October 2026 list prices, a worked cost per prospect, model routing math, and six questions to ask vendors.
- Is AI for sales priced per user or per token?
- What is a token, and why are there two prices?
- AI token costs by model, as of October 2026
- What does one prospect cost? A worked example
- How do batch pricing and prompt caching change the math?
- Does model routing actually work?
- How are AI sales platforms priced?
- Six questions to ask an AI vendor about cost
- Bring your own key: the pros and cons
- How Alpheous handles AI cost
- FAQ
- Sources
In this article
- Is AI for sales priced per user or per token?
- What is a token, and why are there two prices?
- AI token costs by model, as of October 2026
- What does one prospect cost? A worked example
- How do batch pricing and prompt caching change the math?
- Does model routing actually work?
- How are AI sales platforms priced?
- Six questions to ask an AI vendor about cost
- Bring your own key: the pros and cons
- How Alpheous handles AI cost
- FAQ
- Sources
AI token costs for prospecting are small per prospect and large in aggregate, and the biggest lever is which model does which step. In our illustrative example at October 2026 list prices, researching and drafting one prospect entirely on Claude Opus 5.5 costs about 24 cents. Routing research to an inexpensive model and drafting to Sonnet 5.5 brings it to between 2.5 and 3.7 cents.
Is AI for sales priced per user or per token?
It is one of the first questions sales leaders ask about any AI platform: is it priced per user, or, since it's AI and tokens, by usage? Many teams already pay for Claude or ChatGPT seats. The worry is a platform that either charges per head on top of that, or quietly burns tokens nobody can see.
It is the right question. Platforms price in different ways, but underneath all of them sits the same raw material: tokens, billed by a model provider. Understand that layer and you can judge any vendor's pricing on its merits.
What is a token, and why are there two prices?
A token is a chunk of text, usually part of a word, that a model reads or writes and that providers count for billing. Every model has two prices, quoted per million tokens (MTok):
- Input price: everything you send in, including instructions, filings, web pages and prior context.
- Output price: everything the model writes back. On the Gemini models below, "thinking" tokens are billed as output too.
AI token costs by model, as of October 2026
Standard (non-batch) list prices from Anthropic's pricing page and Google's Gemini API pricing page, checked October 2026:
| Model | Input $/MTok | Output $/MTok | Notes |
|---|---|---|---|
| Claude Opus 5.5 | $4.00 | $20.00 | Cache hits $0.20 |
| Claude Sonnet 5.5 | $2.00 | $10.00 | Cache hits $0.10 |
| Claude Haiku 5.5 | $0.10 | $0.50 | Prompts up to 100K tokens; $0.50 / $2.50 above that |
| Gemini 3.8 Flash | $0.75 | $3.75 | Rises to $1.50 / $7.50 on Jan 1, 2027 |
| Gemini 2.5 Flash | $0.30 | $2.50 | Text, image and video input |
| Gemini 2.5 Pro | $1.25 | $10.00 | $2.50 / $15.00 for long prompts |
Two scheduled changes are worth noting. Gemini 3.8 Flash doubles on January 1, 2027, and Google's flagship reasoning model, Gemini 4 Argon, goes from $2 / $10 to $4 / $20 on December 1, 2026. Prices change often, in both directions, so check the linked pricing pages before you budget against any number here.
One more caveat for any LLM cost comparison: tokens are not a fixed unit. Anthropic notes that Claude 4.7 and later models use a newer tokenizer that produces approximately 30% more tokens for the same text, so per-token prices across model generations are not directly comparable. Providers also split text differently. Compare cost per task, not cost per token.
What does one prospect cost? A worked example
This example is illustrative. The token counts are assumptions for a typical research-then-draft job, not measurements from any customer:
- Research step: 40,000 input tokens (a filing extract, a couple of web pages, a press item, instructions) and 2,000 output tokens (a structured summary).
- Drafting step: 6,000 input tokens (the summary, your drafting rules, the angle) and 800 output tokens (one email).
Each cell is input tokens x input price plus output tokens x output price, divided by one million, at the standard prices above. We treat token counts as identical on every model, which they won't quite be. Haiku's 40,000-token research prompt stays under 100K, so its lower rate applies.
| Setup | Research step | Drafting step | Per prospect | Per 1,000 prospects |
|---|---|---|---|---|
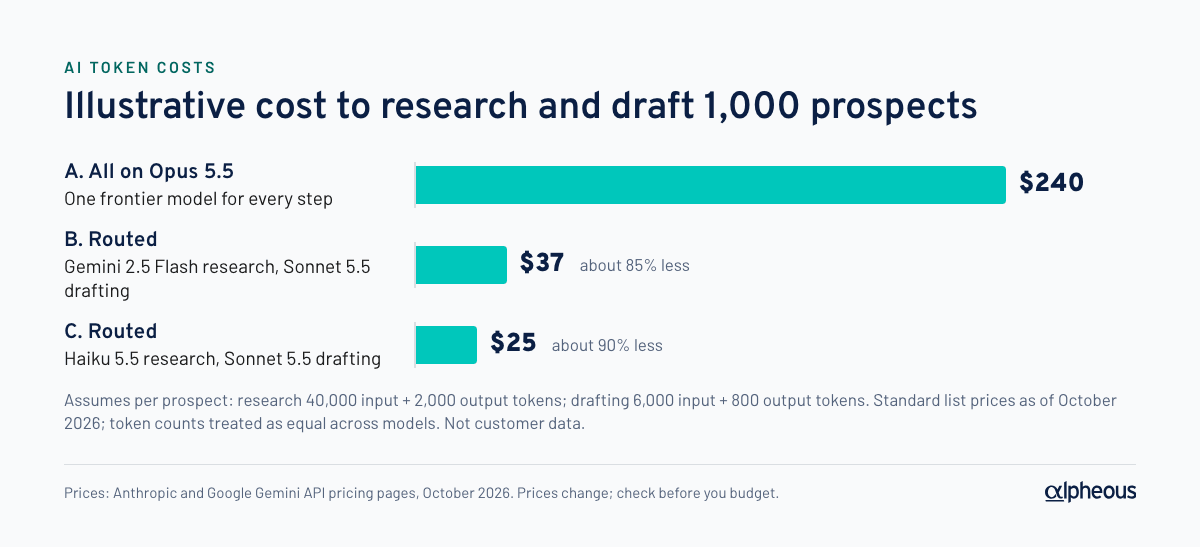
| A. All on Opus 5.5 | $0.160 + $0.040 = $0.200 | $0.024 + $0.016 = $0.040 | $0.240 | $240 |
| B. Gemini 2.5 Flash research, Sonnet 5.5 drafting | $0.012 + $0.005 = $0.017 | $0.012 + $0.008 = $0.020 | $0.037 | $37 |
| C. Haiku 5.5 research, Sonnet 5.5 drafting | $0.004 + $0.001 = $0.005 | $0.012 + $0.008 = $0.020 | $0.025 | $25 |
On these assumptions, setup B costs about 85% less than setup A, and setup C about 90% less. In setup A, research is 83% of the bill, and it is the step that least needs a frontier model.
How do batch pricing and prompt caching change the math?
Two provider features cut costs further without changing the model:
- Batch pricing. Anthropic and Google both take 50% off input and output for batch jobs, which return results later rather than instantly. Overnight research is a natural fit. Run everything through batch and the per-1,000 figures above become $120, $18.50 and $12.50.
- Prompt caching. If every request repeats the same long context (drafting rules, product facts, compliance guidance), caching lets the provider reuse it. On Opus 5.5, cached input reads cost $0.20 per million tokens instead of $4. Check the pricing page for how cache writes are billed before you model it.
Does model routing actually work?
Model routing means sending each task to the cheapest model that can do it well and reserving expensive models for the steps that need them. It is the most effective LLM cost optimization most teams aren't doing.
The research is encouraging. FrugalGPT (Chen, Zaharia and Zou, 2023) found a cascade of models could match the best individual model, GPT-4 at the time, with up to 98% cost reduction in their benchmarks. RouteLLM (LMSYS and UC Berkeley, 2024) reported cost reductions of over 85% on MT Bench while reaching 95% of GPT-4's performance.
Both are research benchmarks on 2023 and 2024 models, and your savings will depend on your tasks. The principle holds: most of a prospecting workflow is reading and summarizing, and inexpensive models do that well.
How are AI sales platforms priced?
Most use one of three models, or a blend:
| Pricing model | How it works | What to watch |
|---|---|---|
| Per seat | A fee per user per month, AI usage bundled | Grows with headcount, not usage; bundled tokens may carry caps or a hidden margin |
| Per platform or feature | A fee for the platform and the capabilities you turn on | What triggers a move to the next tier |
| Usage pass-through | You pay for tokens, via the vendor or your own provider account | Any markup, and whether you can see usage by task |
Six questions to ask an AI vendor about cost
- Whose API keys does it run on? Yours, or the vendor's?
- Who pays for tokens? Included in the fee, billed through, or billed to your own account?
- Is there a markup on tokens? If usage passes through the vendor, at what margin?
- Can you see usage? By task, model and user, not just a monthly total.
- Which model does which task? If the answer is "our best model for everything", you are paying for it somewhere.
- What happens when a provider raises prices? With some Gemini prices doubling on scheduled dates, ask whether you can switch models and who absorbs the change.
Bring your own key: the pros and cons
Bring your own key (BYOK) means a platform runs on your model provider account and API keys rather than the vendor's.
- Pro: you control cost. You see the provider's bill directly and set your own budgets.
- Pro: your data terms. They sit with your provider, under your own account agreement.
- Pro: no markup on tokens.
- Con: you manage billing, rate limits and spending caps with each provider.
- Con: someone has to watch usage and notice when it moves.
How Alpheous handles AI cost
Alpheous uses model routing: inexpensive models do the research and checks, and stronger models do the drafting. Customers run on their own model provider accounts and keys, so they control both cost and data terms. Alpheous is priced by the platform and features you use, not per seat, and it runs as a single-tenant appliance installed on-premise at your firm, so your data stays inside your walls.
If your team still runs every step in a chat app on one model, why AI prospecting workflows in Claude or ChatGPT stall covers the other gaps. See how it works, or book a call to talk through your setup.
FAQ
How much does AI prospecting cost per prospect?
In an illustrative example at October 2026 list prices (40,000 input and 2,000 output tokens for research, 6,000 input and 800 output for drafting), one prospect costs about $0.24 entirely on Claude Opus 5.5. Routing research to Claude Haiku 5.5 or Gemini 2.5 Flash and drafting to Claude Sonnet 5.5 brings it to about $0.025 to $0.037. Your real figure depends on how much text you feed the model at each step.
What is the Claude API cost per million tokens?
As of October 2026, Anthropic lists Claude Opus 5.5 at $4 input and $20 output per million tokens, Sonnet 5.5 at $2 and $10, and Haiku 5.5 at $0.10 and $0.50 for prompts up to 100K tokens. Batch requests are 50% off. Prices change, so check Anthropic's pricing page for current rates.
What is model routing in AI?
Model routing sends each task to the cheapest model that can handle it well and saves expensive models for the steps that need them, such as drafting. Research benchmarks like FrugalGPT and RouteLLM reported large cost reductions at close to top-model quality, though on older models. In prospecting, research and checks suit inexpensive models, while drafting benefits from a stronger one.
What does bring your own key mean for AI tools?
Bring your own key means a software platform runs on your own model provider account and API keys instead of the vendor's. You pay the provider directly with no token markup, and data terms sit under your own agreement. The trade-off is that you manage billing, rate limits and spending caps yourself.
Sources
- Anthropic's pricing page (platform.claude.com)
- Google's Gemini API pricing page (ai.google.dev)
- FrugalGPT (arxiv.org)
- RouteLLM (lmsys.org)
Dave founded Alpheous in 2024 after years of building technology platforms and seeing the same operational bottlenecks across asset management distribution teams.
Dave Ward on LinkedInMore in AI prospecting
Why your AI prospecting workflow in Claude or ChatGPT stalls
Your team uses Claude or ChatGPT, but every AI prospecting workflow still waits for a person. The five gaps to close, a checklist, and a team playbook method.
AI guardrails for BDR outreach: stop the wrong email going out
AI guardrails for BDR outreach in three layers: the six mistakes junior reps make with AI, what causes each, and a checklist to put in place this quarter.
The SEC registration threshold for RIAs is a sales trigger
The SEC registration threshold is $100M-$110M of RAUM. Learn the exact rule, the 90-day and 180-day clocks, and how to spot advisers about to cross it.
Alpheous reads the filings every night and ranks who to call next.